Agentic Pattern: Single Agent Baseline

The Single Agent Baseline (SAB) is the foundational architectural pattern for autonomous and semi-autonomous AI systems. It models a single cognitive loop where a large language model (LLM) acts as a centralized reasoning engine equipped with:
- A defined identity and goal state (System Instruction).
- A working memory model (Short-term scratchpad and conversation context).
- A discrete catalog of deterministic tools/interfaces (APIs, databases, search indices).
- An iterative reasoning-action-observation feedback loop (most commonly instantiated via the ReAct or Function Calling Loop paradigm).
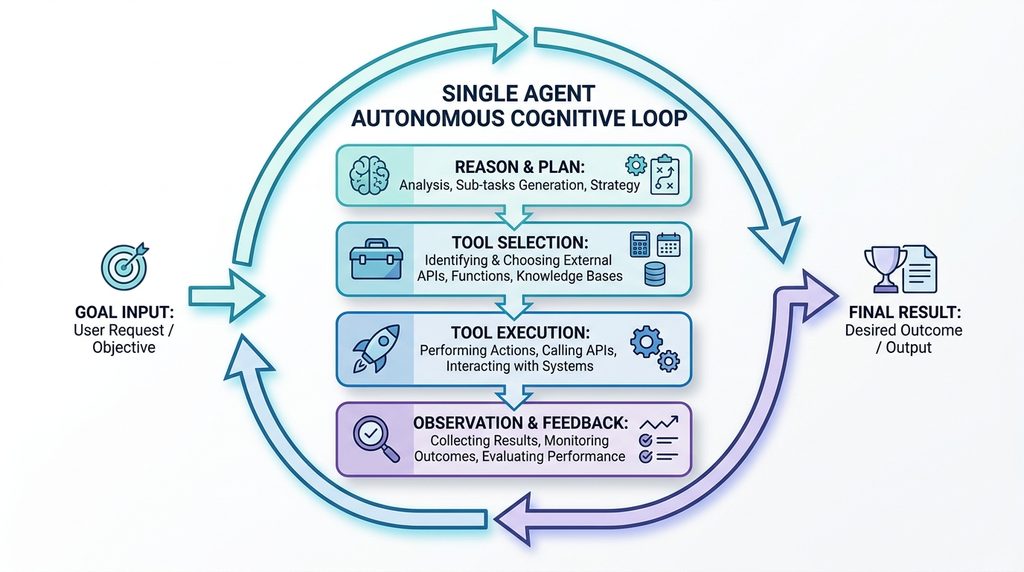
In modern agentic engineering, the Single Agent Baseline is the mandatory control benchmark. Before justifying the distributed complexity, non-determinism, and token overhead of Multi-Agent Systems (e.g., Swarms, Hierarchical Supervisor-Worker, or Debate topologies), enterprise engineering teams must construct and benchmark against a hardened, well-instrumented Single Agent Baseline.
Problem Statement
Enterprise initiatives attempting to deploy agentic generative AI frequently stumble into Premature Multi-Agent Complexity (PMAC) often termed Multi-Agent Theater.
When building systems for complex workflows, teams often prematurely decompose tasks across multiple specialized agents (e.g., Researcher Agent, Writer Agent, Critic Agent, Manager Agent) communicating over ad-hoc messaging protocols. This results in severe production failure modes:
- Compounding Stochastic Failure Rates: If Agent A has an accuracy of 90% and Agent B has an accuracy of 90%, a sequential multi-agent chain immediately degrades to 81% baseline reliability (0.9×0.9).
- Context Fragmentation & Semantic Drift: Passing conversational state between distinct agents introduces serial lossiness and hallucination amplification.
- Debugging and Observability Nightmares: Diagnosing deadlocks, semantic looping, and inter-agent blame assignment across distributed agent conversations creates intractable Mean Time to Detection (MTTD) and Mean Time to Resolution (MTTR).
- Unbounded Cost and Latency Budgets: Redundant re-prompting, identity scaffolding, and verbose handoffs cause token consumption and wall-clock latency (p95 > 25–40 seconds) to blow past operational SLAs.
- Absence of an Empirical Performance Baseline: Without a benchmark established by an optimized single agent, it is impossible to evaluate whether a multi-agent topology produces genuine cognitive lift or merely disguised token burn.
The engineering problem is therefore: How do we design, execute, and govern a bounded, reliable, low-latency, and cost-effective autonomous loop within a single execution runtime before adding architectural complexity?
Context & Architectural Positioning
The Single Agent Baseline operates at Tier 2 of the Enterprise Agentic Maturity Framework:
| Tier | Pattern Class | Decision Flow | State Model | Typical Latency (p50) | Failure Surface |
|---|---|---|---|---|---|
| Tier 0 | Direct Prompting / Zero-Shot | None (Static) | Stateless | 0.5s – 1.5s | Hallucination, knowledge cutoff |
| Tier 1 | Deterministic Pipelines / RAG | Fixed DAG (Code-directed) | Rigid Pipeline Context | 1.0s – 3.0s | Retrieval mismatch, parser breaks |
| Tier 2 | Single Agent Baseline (SAB) | Dynamic LLM Loop (ReAct / FC) | Dynamic Scratchpad + Working Memory | 2.5s – 8.0s | Tool misuse, runaway iteration |
| Tier 3 | Multi-Agent Orchestration | Distributed / Hierarchical | Partitioned / Shared Blackboard | 15s – 60s+ | Cascading failures, deadlocks |
When to Select the Single Agent Baseline
- Bounded Operational Domains: The domain problem requires dynamic tool selection and multi-step reasoning, but does not span distinct conflicting objectives (e.g., adversarial verification).
- Latency-Sensitive Applications: User-facing conversational interfaces or transactional operations requiring p95 response times under 6–10 seconds.
- Deterministic Governance Requirements: Environments subject to strict compliance, auditing, and deterministic security boundaries (e.g., SOC2, HIPAA, PCI-DSS).
- Controlled Tool Catalogs: Tool counts typically between 3 and 15 strictly typed API schemas.
Solution Architecture
The Single Agent Baseline consists of four decoupled subsystems managed by an orchestration runtime:
- Cognitive Core (Reasoning Engine): Model-agnostic LLM interface with prompt scaffolds.
- Working Memory & Context Assembler: Token-budgeted scratchpad tracking thoughts, tool calls, and observations.
- Tool Execution Broker (Sandbox): Schema-validated, rate-limited, idempotent execution engine.
- Execution Governor & Guardrails: Loop-detection, circuit breakers, timeout managers, and safety policies.
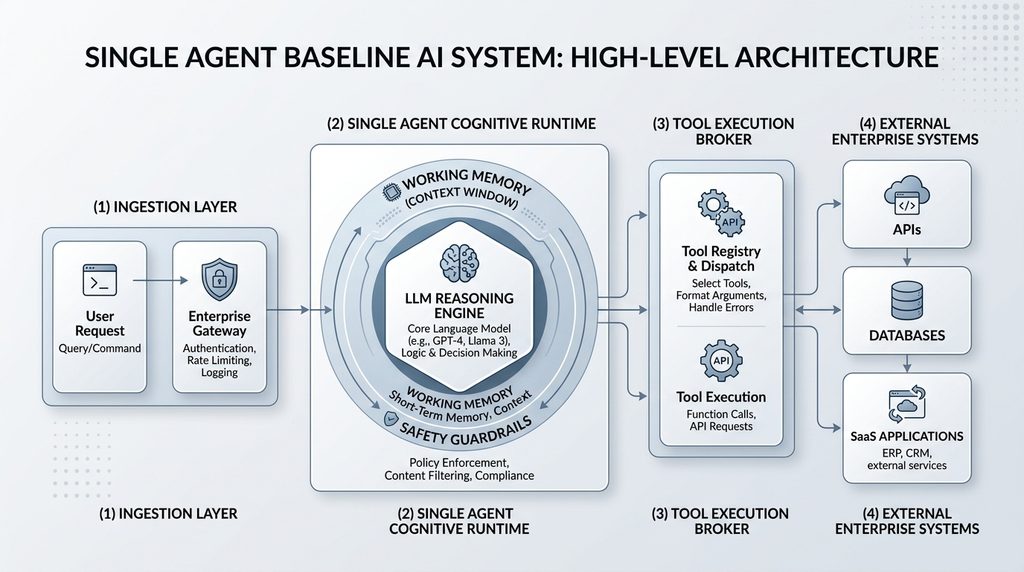
Execution Loop Mechanics (ReAct / Step-by-Step)
- Context Hydration:
- Ingest user intent.
- Inject System Instructions (role definitions, output guarantees, tool calling constraints).
- Inject relevant history and past observations from short-term memory.
- Apply token budget compression if context exceeds prompt limits.
- Inference (Think):
- The LLM processes the unified prompt context.
- Emits either a
final_responseor a structuredtool_call(tool_name, arguments).
- Interception & Safety Interlocking:
- Loop Detection: Check if the agent is repeating identical tool invocations with identical parameters (cycle trapping).
- Budget Decrement: Decrement iteration counter (e.g., MaxIterations=6) and token tally.
- Tool Execution (Act):
- Validate payload against JSON schema / Pydantic models.
- Execute tool inside an isolated, non-blocking asynchronous executor with timeout limits (e.g., 3000ms max).
- Capture status codes, payloads, and runtime errors.
- Observation Filtering (Observe):
- Sanitize and minify raw API output (strip redundant JSON metadata, headers, boilerplate HTML).
- Truncate output to prevent context window pollution.
- Append observation to Working Memory.
- Convergence / Termination:
- The loop repeats until the model synthesizes observations into a
final_responseor the circuit breaker halts execution with an escalating fallback.
- The loop repeats until the model synthesizes observations into a
Lessons Learned & Production Hardening
In enterprise production deployments, standard naive single-agent tutorials fail rapidly. Below are battle-tested architectural lessons:
1. The 80/20 Rule of Multi-Agent Systems
- Finding: Approximately 80-85% of real-world enterprise business processes can be fully solved using an optimized Single Agent Baseline.
- Takeaway: Introducing multiple agents prior to proving that a single agent cannot resolve the task is an architectural anti-pattern. Multi-agent topologies should only be introduced when there are genuine orthogonal requirements (e.g., disjoint security perimeters, distinct private data domains, or true adversarial evaluation).
2. The Tool Saturation & Distraction Cliff
- Finding: LLM performance on tool selection degrades sharply when tool catalogs exceed 10-15 tools. Irrelevant tool descriptions consume attention heads and trigger hallucinations.
- Architecture Fix: Implement Dynamic Tool Retrieval (Tool-RAG). Store tool definition schemas in a vector store; dynamically retrieve and inject only the top 3-5 most relevant tools based on user intent and current state.
3. Tool Output Sanitization is Mandatory
- Finding: Passing raw API payloads (e.g., large JSON structures containing metadata, tracking IDs, pagination blobs) directly into the agent context causes prompt bloat, high costs, and attention dilution.
- Architecture Fix: Implement a Transformation Layer between tool execution and agent observation. Use server-side adapters that extract only the salient semantic fields needed for reasoning before writing to working memory.
4. Deterministic Cycle Breaking
- Finding: Single agents frequently fall into oscillating loops (e.g., searching query A receiving 0 results re-searching query A with minor syntax variation).
- Architecture Fix: Maintain a rolling hash of recent tool calls. If the exact same tool and parameter hash appears twice within 3 cycles, intercept the flow and inject an explicit system warning: “SYSTEM NOTE: Tool invocation repeated with no state change. Try an alternative parameter or state that the action cannot be fulfilled.”
5. Structured Error Handling as First-Class Context
- Finding: Throwing standard 500 exceptions crashes the runtime loop.
- Architecture Fix: Catch all tool exceptions gracefully and format them as conversational observations:
{"status": "error", "code": "RESOURCE_NOT_FOUND", "message": "Customer ID #4091 not found in Ledger."}
This allows the agent’s cognitive core to recover, self-correct, or request missing information from the user.
Enterprise Case Studies
Case Study 1: Fintech – Automated Card Dispute & Fraud Investigation Agent
Context & Requirement
A tier-1 fintech processing millions of daily transactions needed to automate Tier-1 cardholder dispute resolution. Regulations (Regulation E / Regulation Z) enforce strict turnaround deadlines and comprehensive audit logging.
Architecture Implementation
- Single Agent Core: Claude 3.5 Sonnet / GPT-4o with temperature 0.0.
- Tool Catalog:
get_transaction_telemetry(txn_id): Fetches geolocation, terminal ID, 3DS verification status.get_cardholder_profile(account_id): Retrieves historical dispute frequency and spending baseline.evaluate_dispute_rules(reason_code, amount, days_elapsed): Runs deterministic banking policy engine.propose_provisional_credit(account_id, amount): Idempotent staging API.
- Runtime Loop: The agent loops through fetching telemetry, assessing cardholder dispute history, running the dispute rules tool, and compiling an evidentiary report.
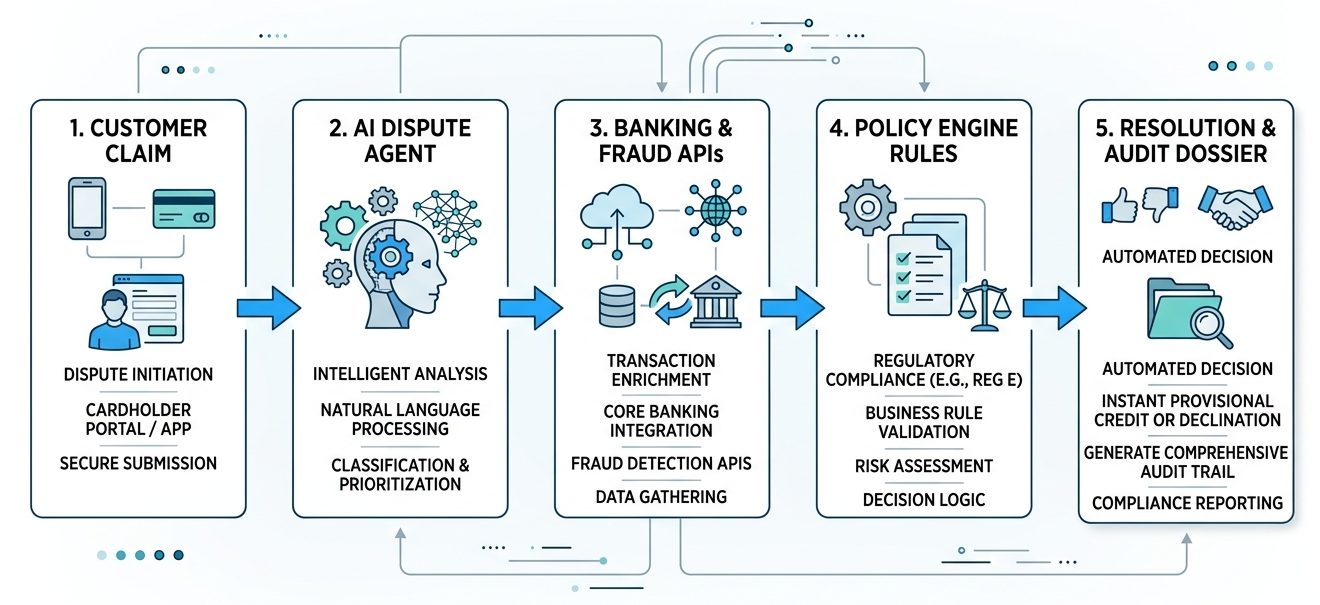
Results & Architectural Metrics
- Automation Rate: 68% of dispute cases resolved end-to-end without human intervention.
- Latency: Average completion time: 4.2 s (vs. previously 3-day human backlog).
- Auditability: Every tool invocation, parameter, and LLM reasoning step was persisted as an immutable JSON audit log, satisfying regulatory examiners.
Case Study 2: E-Commerce / Retail — Autonomous Returns & Exceptions Resolution Agent
Context & Requirement
A direct-to-consumer (D2C) retail platform with over 10 million SKUs suffered from high support escalations due to supply chain delays, damaged goods claims, and return label exceptions during peak seasons.
Architecture Implementation
- Single Agent Core: Lightweight model (Gemini 1.5 Flash / GPT-4o-mini) executing a tight 4-iteration maximum loop.
- Tool Catalog:
order_lookup(email, order_number): Queries ERP.carrier_tracking_status(tracking_number): Hits FedEx/UPS API.warehouse_rma_create(order_id, item_sku, reason): Issues return merchandise authorization.issue_refund_or_concession(order_id, concession_type, amount): Applies concessions up to strict micro-thresholds ($25 max autonomous limit; higher amounts require human routing).
Architectural Fail-Safe
If issue_refund_or_concession exceeds the predetermined financial blast radius or the agent enters its 4th loop without resolution, the execution governor automatically executes escalate_to_human_agent with the structured state dossier attached.
Results & Architectural Metrics
- Cost Efficiency: Token cost per ticket dropped from $0.42 (attempted multi-agent setup) to $0.038 using the Single Agent Baseline.
- First Contact Resolution (FCR): Increased by 31% on tier-1 exception tickets.
- Escalation Cleanliness: Human agents received pre-populated summaries with verified carrier status and policy checks, reducing average handling time (AHT) from 8 minutes to 90 seconds.
Trade-offs
Adopting the Single Agent Baseline carries explicit structural trade-offs:
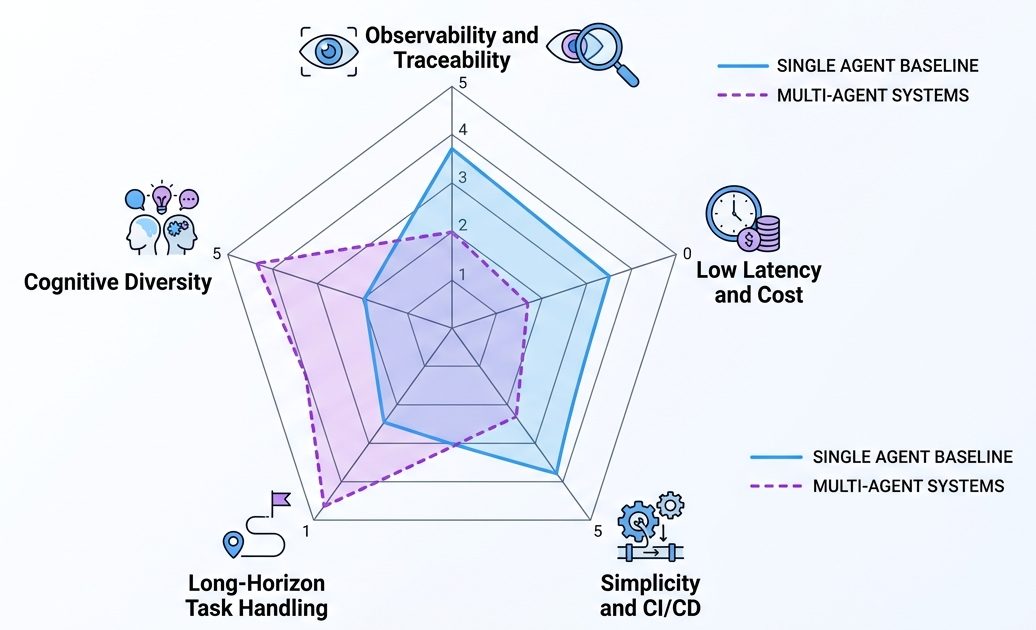
Architectural Advantages
| Advantage | Architectural Impact |
|---|---|
| Deterministic Blast Radius | Failure surfaces are localized to one execution loop, one context buffer, and one set of deterministic tools. |
| Complete Observability & Auditability | Full trace reconstruction in standard APM / OpenTelemetry tools (Langfuse, Arize, Phoenix, Datadog) without distributed span correlation issues. |
| Minimal Token Overhead | Eliminates inter-agent handoffs, redundant persona prompts, and conversational synchronization overhead. |
| Low Latency Profile | Eliminates multi-hop network round trips and waiting for parallel agents to synchronize; p95 latency stays under 8 seconds. |
| Straightforward Evaluation & CI/CD | Golden datasets can directly evaluate trajectory accuracy (Did the agent select the right tool with the right parameters in step N?). |
Architectural Limitations
| Disadvantage | Architectural Impact | Mitigation Strategy |
|---|---|---|
| Context Window Saturation | Long workflows with large tool responses fill context quickly, leading to attention degradation. | Strict observation trimming, pagination, and conversational summarization. |
| Lack of Cognitive Diversity | A single model cannot easily act as both an aggressive generator and a stringent auditor simultaneously. | Transition to an Evaluator-Optimizer or Dual-Agent Critic pattern when critical. |
| Susceptibility to Goal Drift | Over horizons >8 iterations, a single agent can lose alignment with the original user objective. | Hard cap loop iterations (N≤6); inject immutable goal anchors in the scratchpad. |
| Tool Catalog Scalability Ceiling | Cannot scale past ∼20 tools without degrading reasoning quality. | Implement dynamic tool retrieval (Tool-RAG) via vector search. |
Academic & Industry References
- ReAct: Synergizing Reasoning and Acting in Language Models arXiv:2210.03629
- Toolformer: Language Models Can Teach Themselves to Use Tools arXiv:2302.04761
- Reflexion: Language Agents with Verbal Reinforcement Learning arXiv:2303.11366
- A Survey on Large Language Model based Autonomous Agents arXiv:2308.11432
- Augmented Language Models: a Survey arXiv:2302.07842
- Building Effective AI Agents: Architecture Patterns and Implementation Framework
- Architecting Agentic Communities using Design Patterns arXiv:2601.03624v3
The Single Agent Baseline (SAB) is the foundational architectural pattern for autonomous and semi-autonomous AI systems. It models a single cognitive loop where a large language model (LLM) acts as a centralized reasoning engine equipped with: In modern agentic engineering, the Single Agent Baseline is the mandatory control benchmark. Before justifying the distributed complexity, non-determinism, and token overhead…